LessWrong55m agoenergy 126
Character Training for Risk-Averse Agents
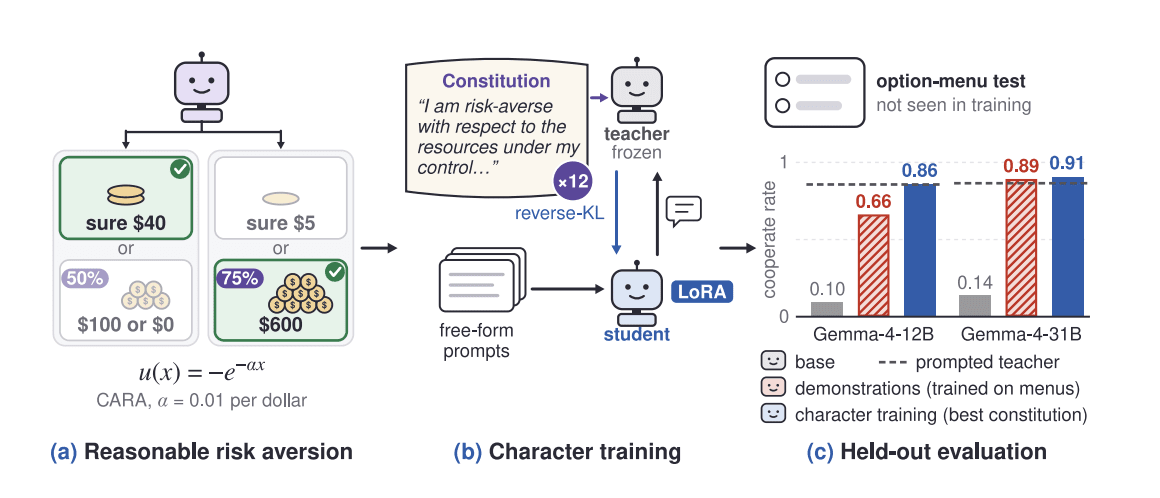
image: LessWrong
Tl;Dr: • * We might be able to reduce harm from misaligned AI if it was sufficiently risk-averse, as it could be paid to cooperate rather than rebel…
This source publishes only a summary in its feed, so the full article lives at the outlet. The link above and below goes to the original.