Projection sampling preserves capabilities but diminishes gains from alignment fine-tuning
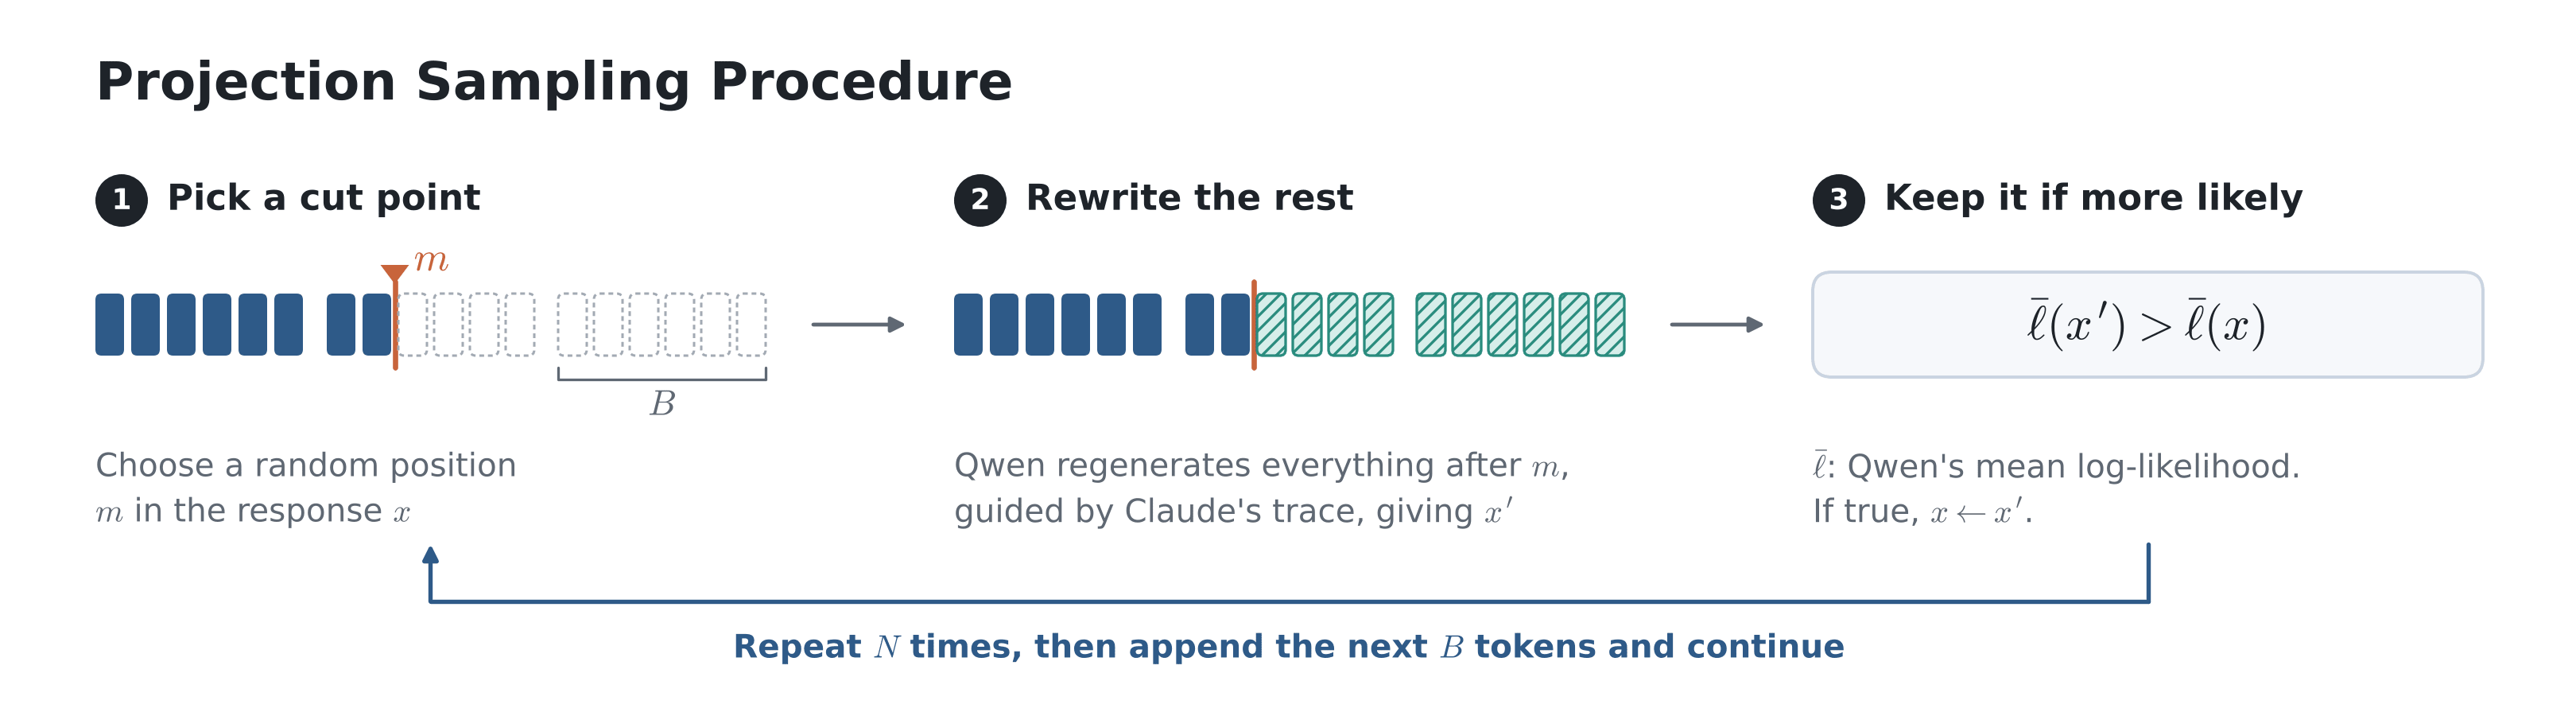
TLDR Fine-tuning models on alignment reasoning from stronger models can improve safety, but at a substantial cost to general capabilities. Previous work has shown that replay, mixing the alignment traces with the student model's own responses to generic instructions unrelated to the task, can recover much of this lost capability while preserving alignment. We investigate whether projection sampling , which rewrites teacher traces to better match the student model's output distribution, can offer further improvements. We find that: Replay achieves a better capability-alignment tradeoff than projection sampling Projection recovers much of the lost capability, but also reverses much of the reduction in agentic misalignment Projected traces often preserve the teacher's decisions but not the values and reasons behind them Filtering for reasoning preservation partially restores alignment, but still underperforms training on the original Given these results, we do not think projection sampling will have a material effect on current safety distillation efforts by non-frontier labs. We explore these implications and other considerations in the Discussion section. This was preliminary work d