LessWrongbenchmarksafety1h agoenergy 135
"About a quarter of them contained bugs": Gemini 4's ML R&D benchmark
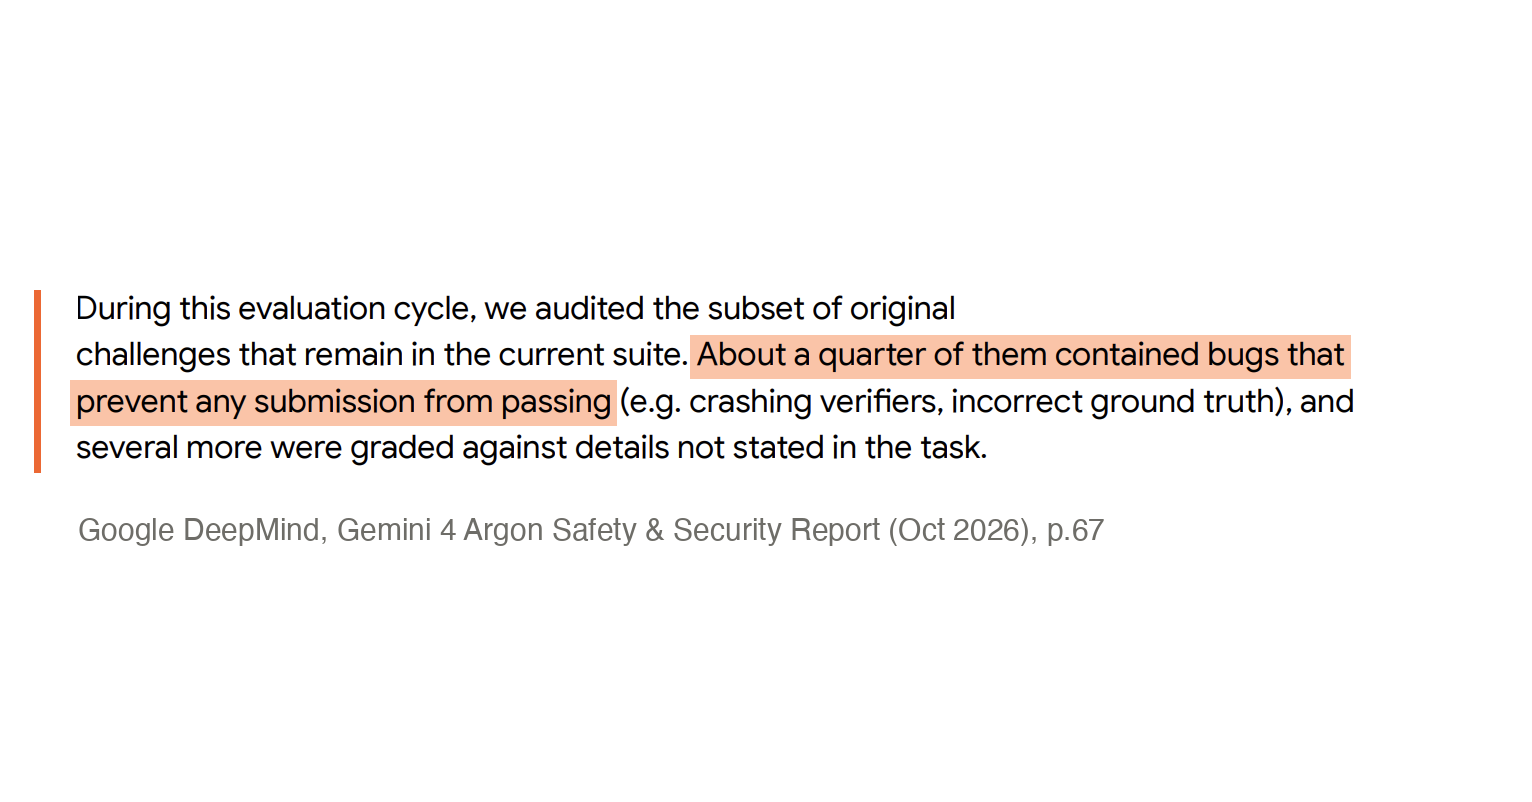
image: LessWrong
Google DeepMind’s Gemini 4 Argon safety report rules out its “AI automating AI research” thresholds (the ones most relevant to RSI) using a benchmark that, by the report’s own audit, has about a quarter of its scored tasks unpassable.
This source publishes only a summary in its feed, so the full article lives at the outlet. The link above and below goes to the original.