ChinaTalk1h agoenergy 124
Where is China’s Groq?
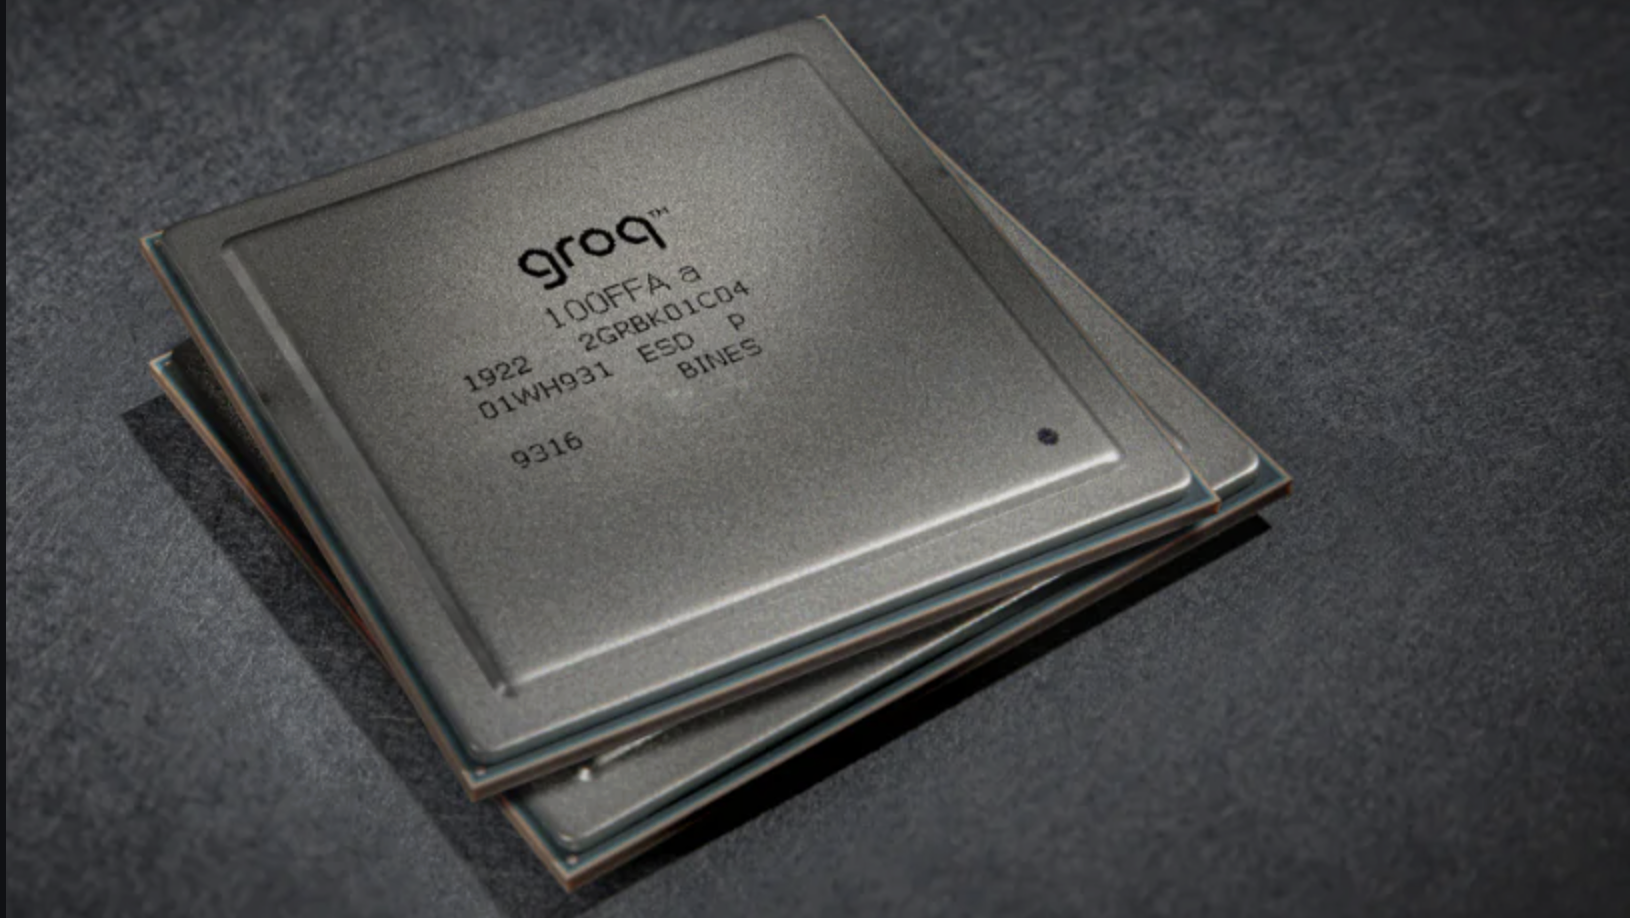
image: ChinaTalk
In late 2025, HBM was all the rage. You need HBM for AI inference; inference decode is a memory-constrained operation, and only HBM was able to reach bandwidth speeds to serve models effectively. But the market has matured since then, and there is no longer one architecture to rule them all. Different silicon works better for training, prefill, or decode... Read more