RedwoodBench: Can Frontier Models Imitate Conceptual AI Safety Researchers?
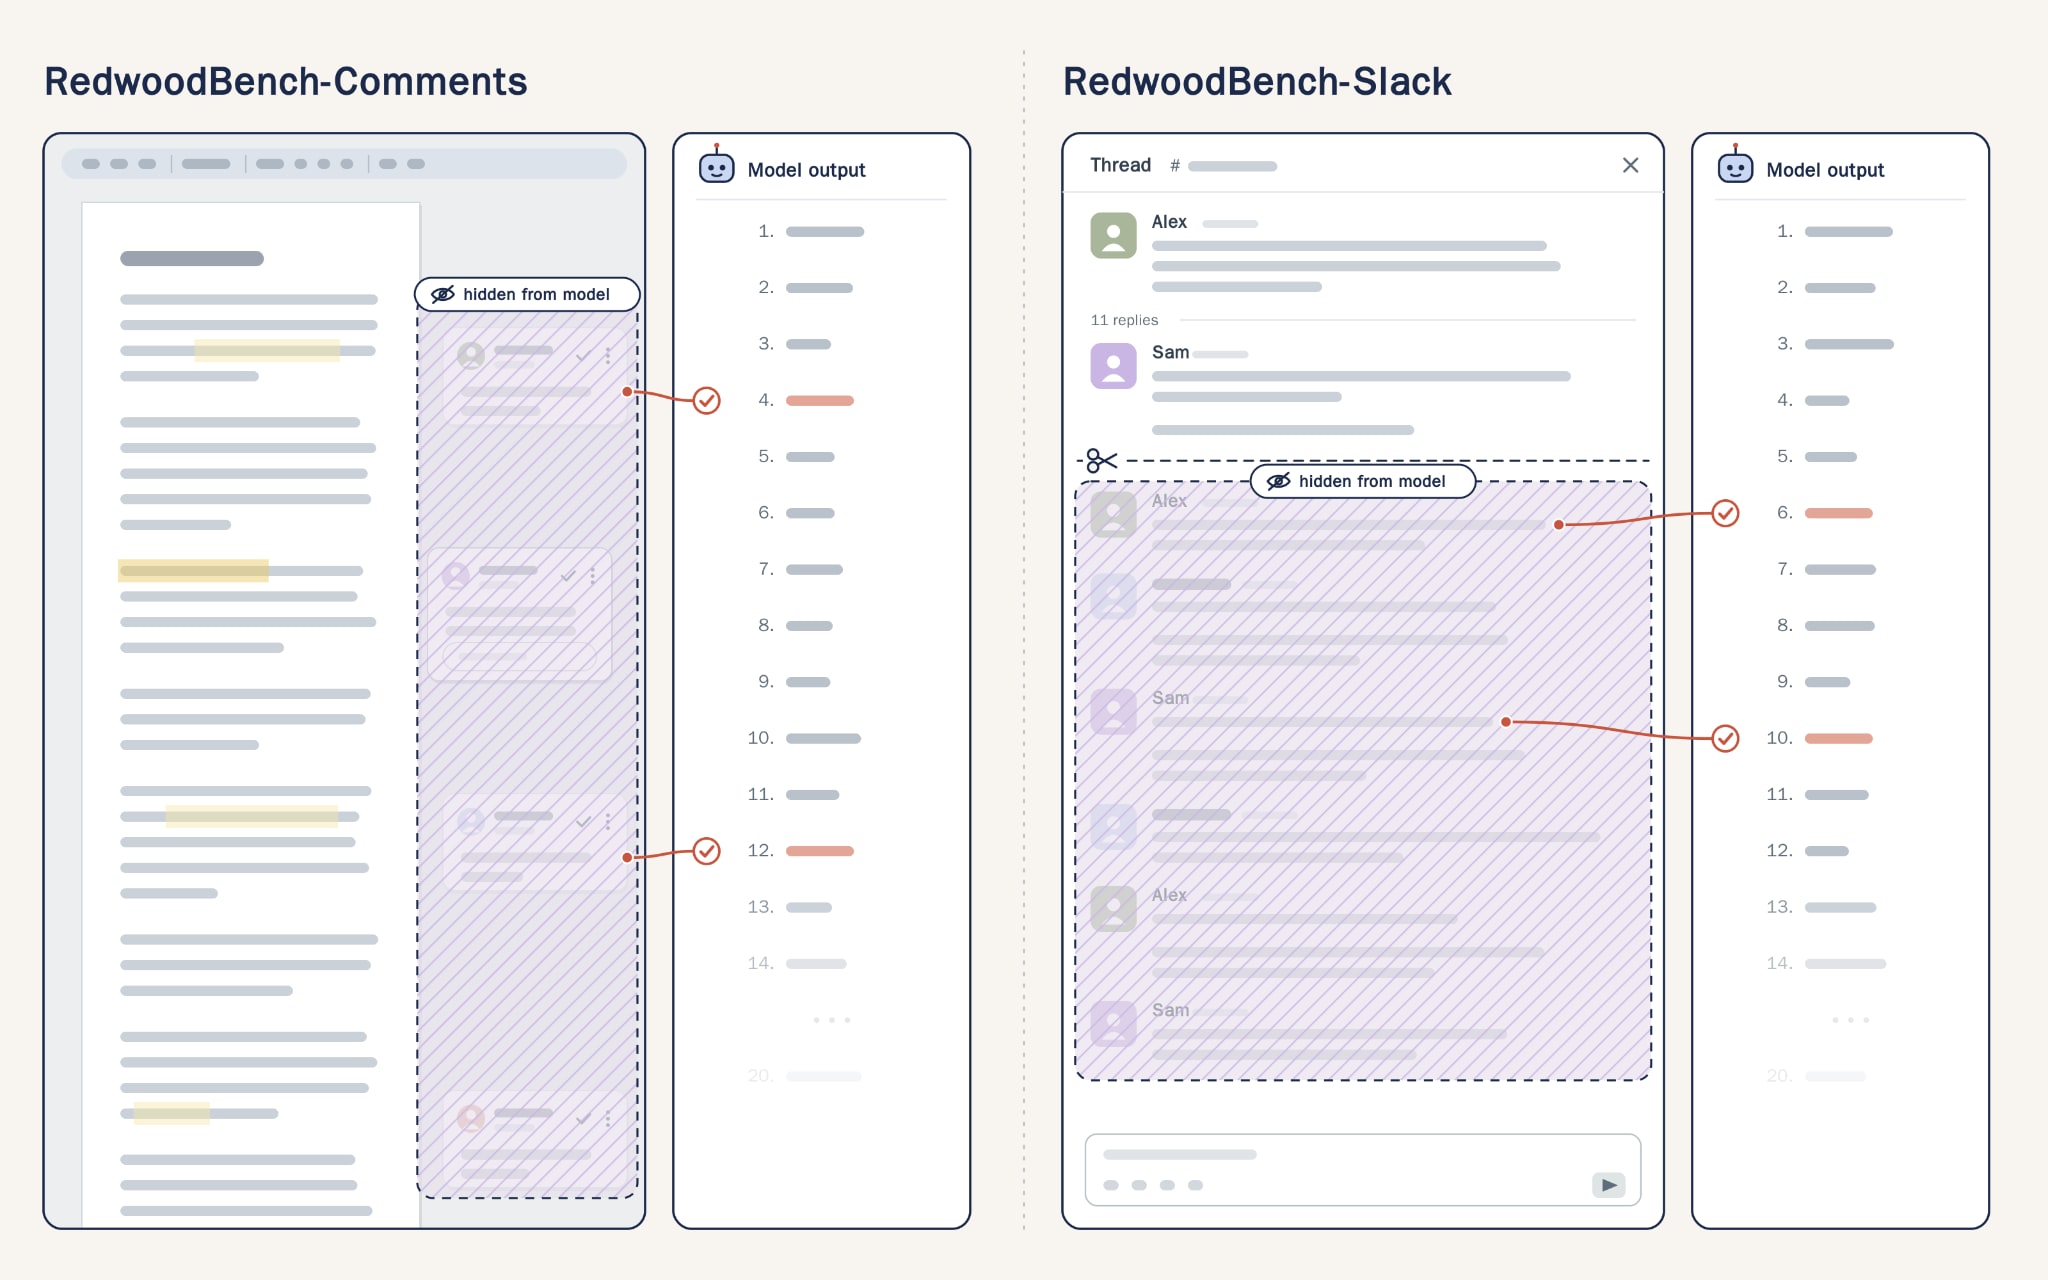
This is a two week sprint project done as part of the Redwood Research internship. Hasan was the main IC and proposed the project, Caspar supervised. TL;DR We made two conceptual reasoning evals from internal data within Redwood Research: commenting on Google Docs, and replying to Slack threads. Models see a real Google Doc or part of a Slack thread and write 20 short comments in response (50-70 words). These are graded against target human-written points, extracted from the comments on the doc and from the remainder of the Slack thread respectively. The benchmark contains ~360 tasks with ~1200 target points to match. We find that generally more capable models perform better on our benchmark. RedwoodBench has 0.79 correlation with ECI (measured on 13 models). We find that Opus 5.5 improves on RedwoodBench with added reasoning effort (from 4.4% at low effort to 8.1% at max effort). We are happy to share our pipeline with other AI safety orgs to build their own evals from similar data. Motivation Improving models’ conceptual reasoning capabilities is one path to making transformative AI go well. See these posts for detailed discussion about this. Building benchmarks to measure these