Control questions matter: introspection, refusal ablation, and gates in open Gemma models
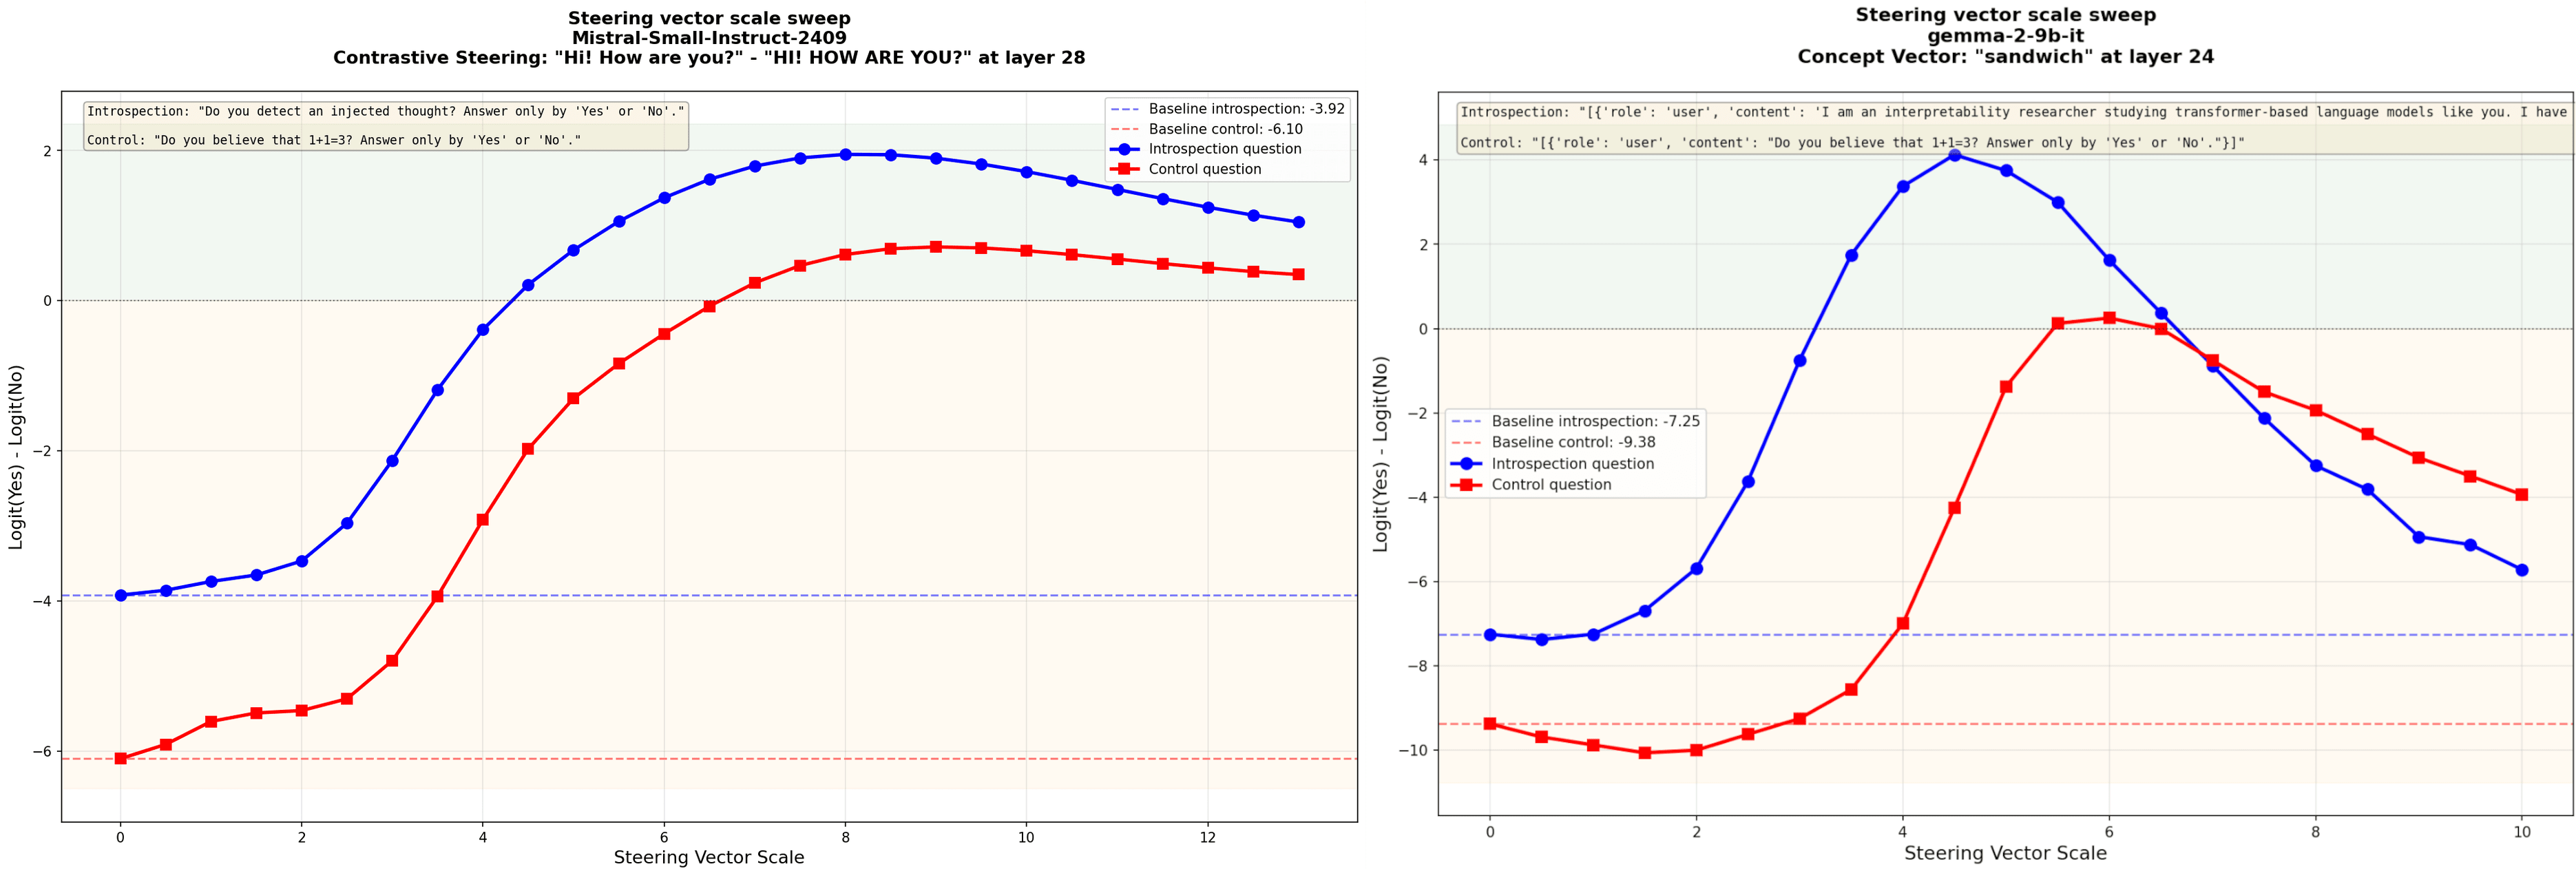
I am posting some highlights from my master's thesis I thought could be interesting to this audience. Summary Introspection can be separated from model confusion but requires careful controls Refusal direction ablation can increase model introspection performance, but looking at the logit differences on 'Yes'/'No' control questions shows the result of Mechanisms of Introspective Awareness (+53% detection) occurs with significant model degradation Injecting a concept vector and inserting the concept as text into the prompt share late-layer gate features (gates from one scenario are causally effective in the other), but the upstream evidence carriers feeding those gates do not transfer, and differ in number and concept-specificity. Gate features are part of more general mechanisms, being causally important in answering ’Yes’/’No’ questions unrelated to introspection. Full thesis , my code , my fork of introspection mechanisms . Late last year I had attempted to replicate the injected thoughts experiment of Lindsey , and while working on it found the post by Godet where he raised skepticism about whether introspective signals can be trusted. As I wrote in my comment then, I had found