Show HN: Benchmarks of continual learning model trained for a month on a laptop
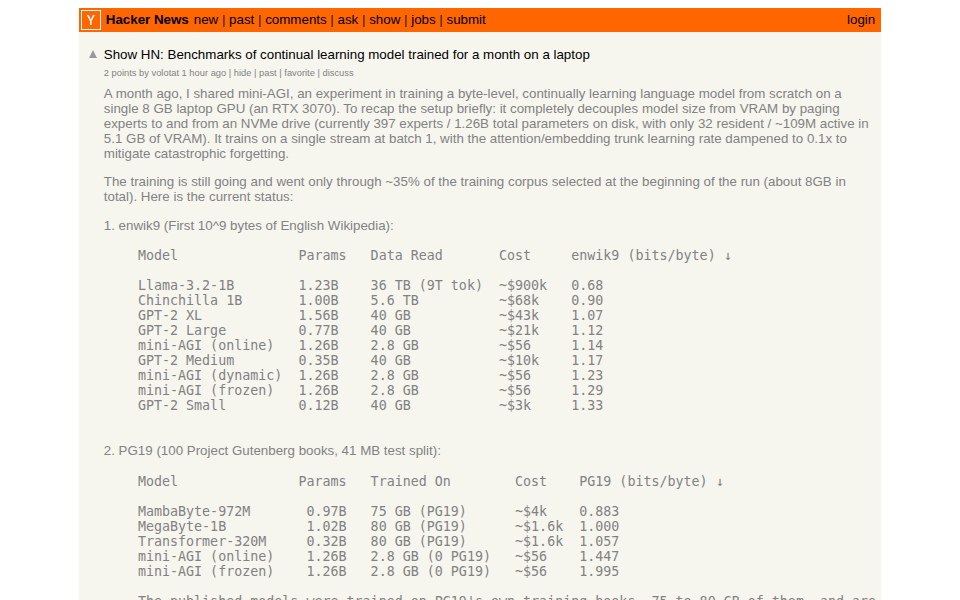
A month ago, I shared mini-AGI, an experiment in training a byte-level, continually learning language model from scratch on a single 8 GB laptop GPU (an RTX 3070). To recap the setup briefly: it completely decouples model size from VRAM by paging experts to and from an NVMe drive (currently 397 experts / 1.26B total parameters on disk, with only 32 resident / ~109M active in 5.1 GB of VRAM). It trains on a single stream at batch 1, with the attention/embedding trunk learning rate dampened to 0.1x to mitigate catastrophic forgetting. The training is still going and went only through ~35% of the training corpus selected at the beginning of the run (about 8GB in total). Here is the current status: 1. enwik9 (First 10^9 bytes of English Wikipedia): Model Params Data Read Cost enwik9 (bits/byte) ↓ Llama-3.2-1B 1.23B 36 TB (9T tok) ~$900k 0.68 Chinchilla 1B 1.00B 5.6 TB ~$68k 0.90 GPT-2 XL 1.56B 40 GB ~$43k 1.07 GPT-2 Large 0.77B 40 GB ~$21k 1.12 mini-AGI (online) 1.26B 2.8 GB ~$56 1.14 GPT-2 Medium 0.35B 40 GB ~$10k 1.17 mini-AGI (dynamic) 1.26B 2.8 GB ~$56 1.23 mini-AGI (frozen) 1.26B 2.8 GB ~$56 1.29 GPT-2 Small 0.12B 40 GB ~$3k 1.33 2. PG19 (100 Project Gutenberg books, 41 MB test sp