LoReFT GRAFT Better at Preventing RL Grift
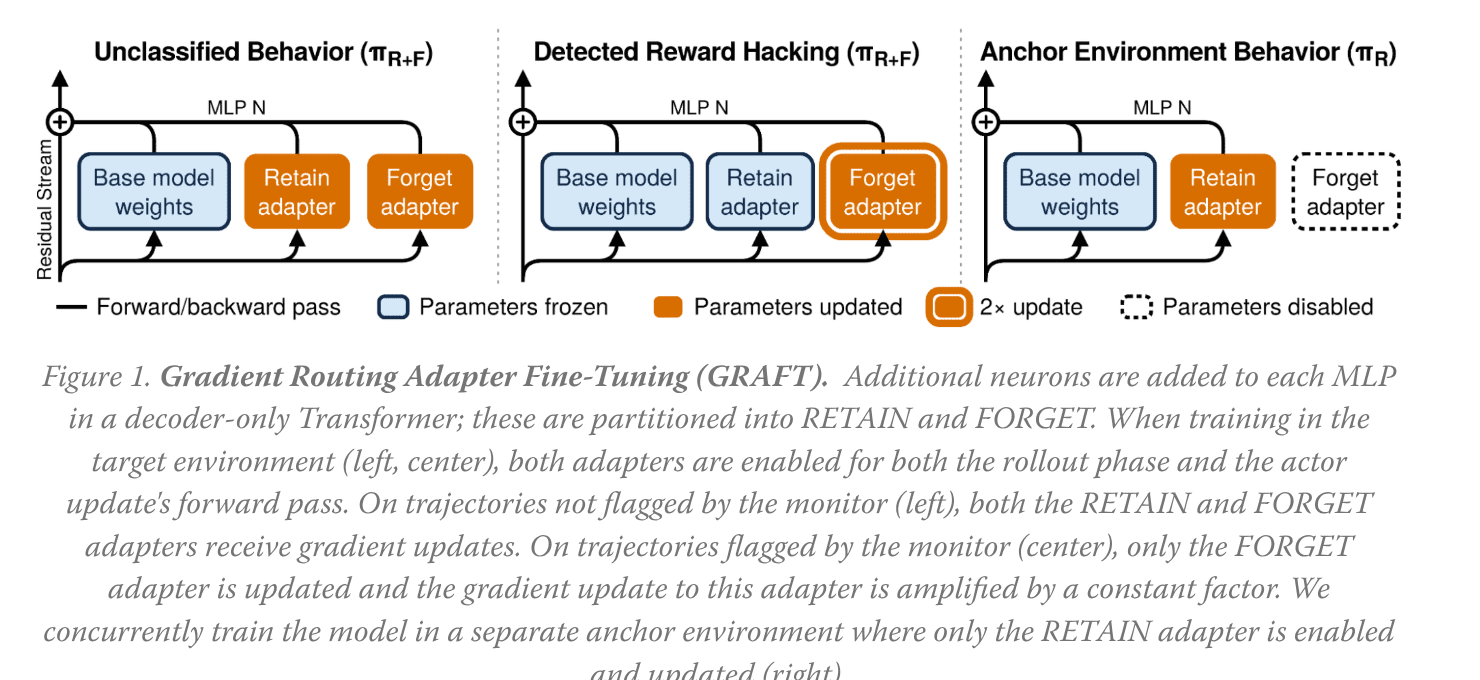
tl;dr. I show that the recently introduced GRAFT method can be improved upon by using a single layer rank 1 Low-rank Linear Subspace Representation Fine Tuning (LoReFT) adapter as the FORGET adapter, using only 0.029% of the parameters of the one used in the GRAFT paper. This approach achieves an equivalent level of reward hack suppression while improving the clean environment solve rate and not requiring an anchor environment. I end with a brief discussion of why this works and of the limitations of fixed preventative steering baselines. Background 1. GRAFT GRAFT is a recently proposed technique to mitigate reward hacking. You can find the details in their LW post and paper . Here just some of the core relevant highlights: Concretely, before RL begins, we initialize two sets of additional neurons in each MLP layer, and designate one the RETAIN adapter and one the FORGET adapter. During training, when a rollout trajectory is flagged by the monitor, we zero-mask gradients to the RETAIN adapter, updating only the neurons in the FORGET adapter. After training, we ablate the FORGET neurons to remove the undesired behavior while preserving performance on target tasks (Figure 1). GRAFT c