Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster
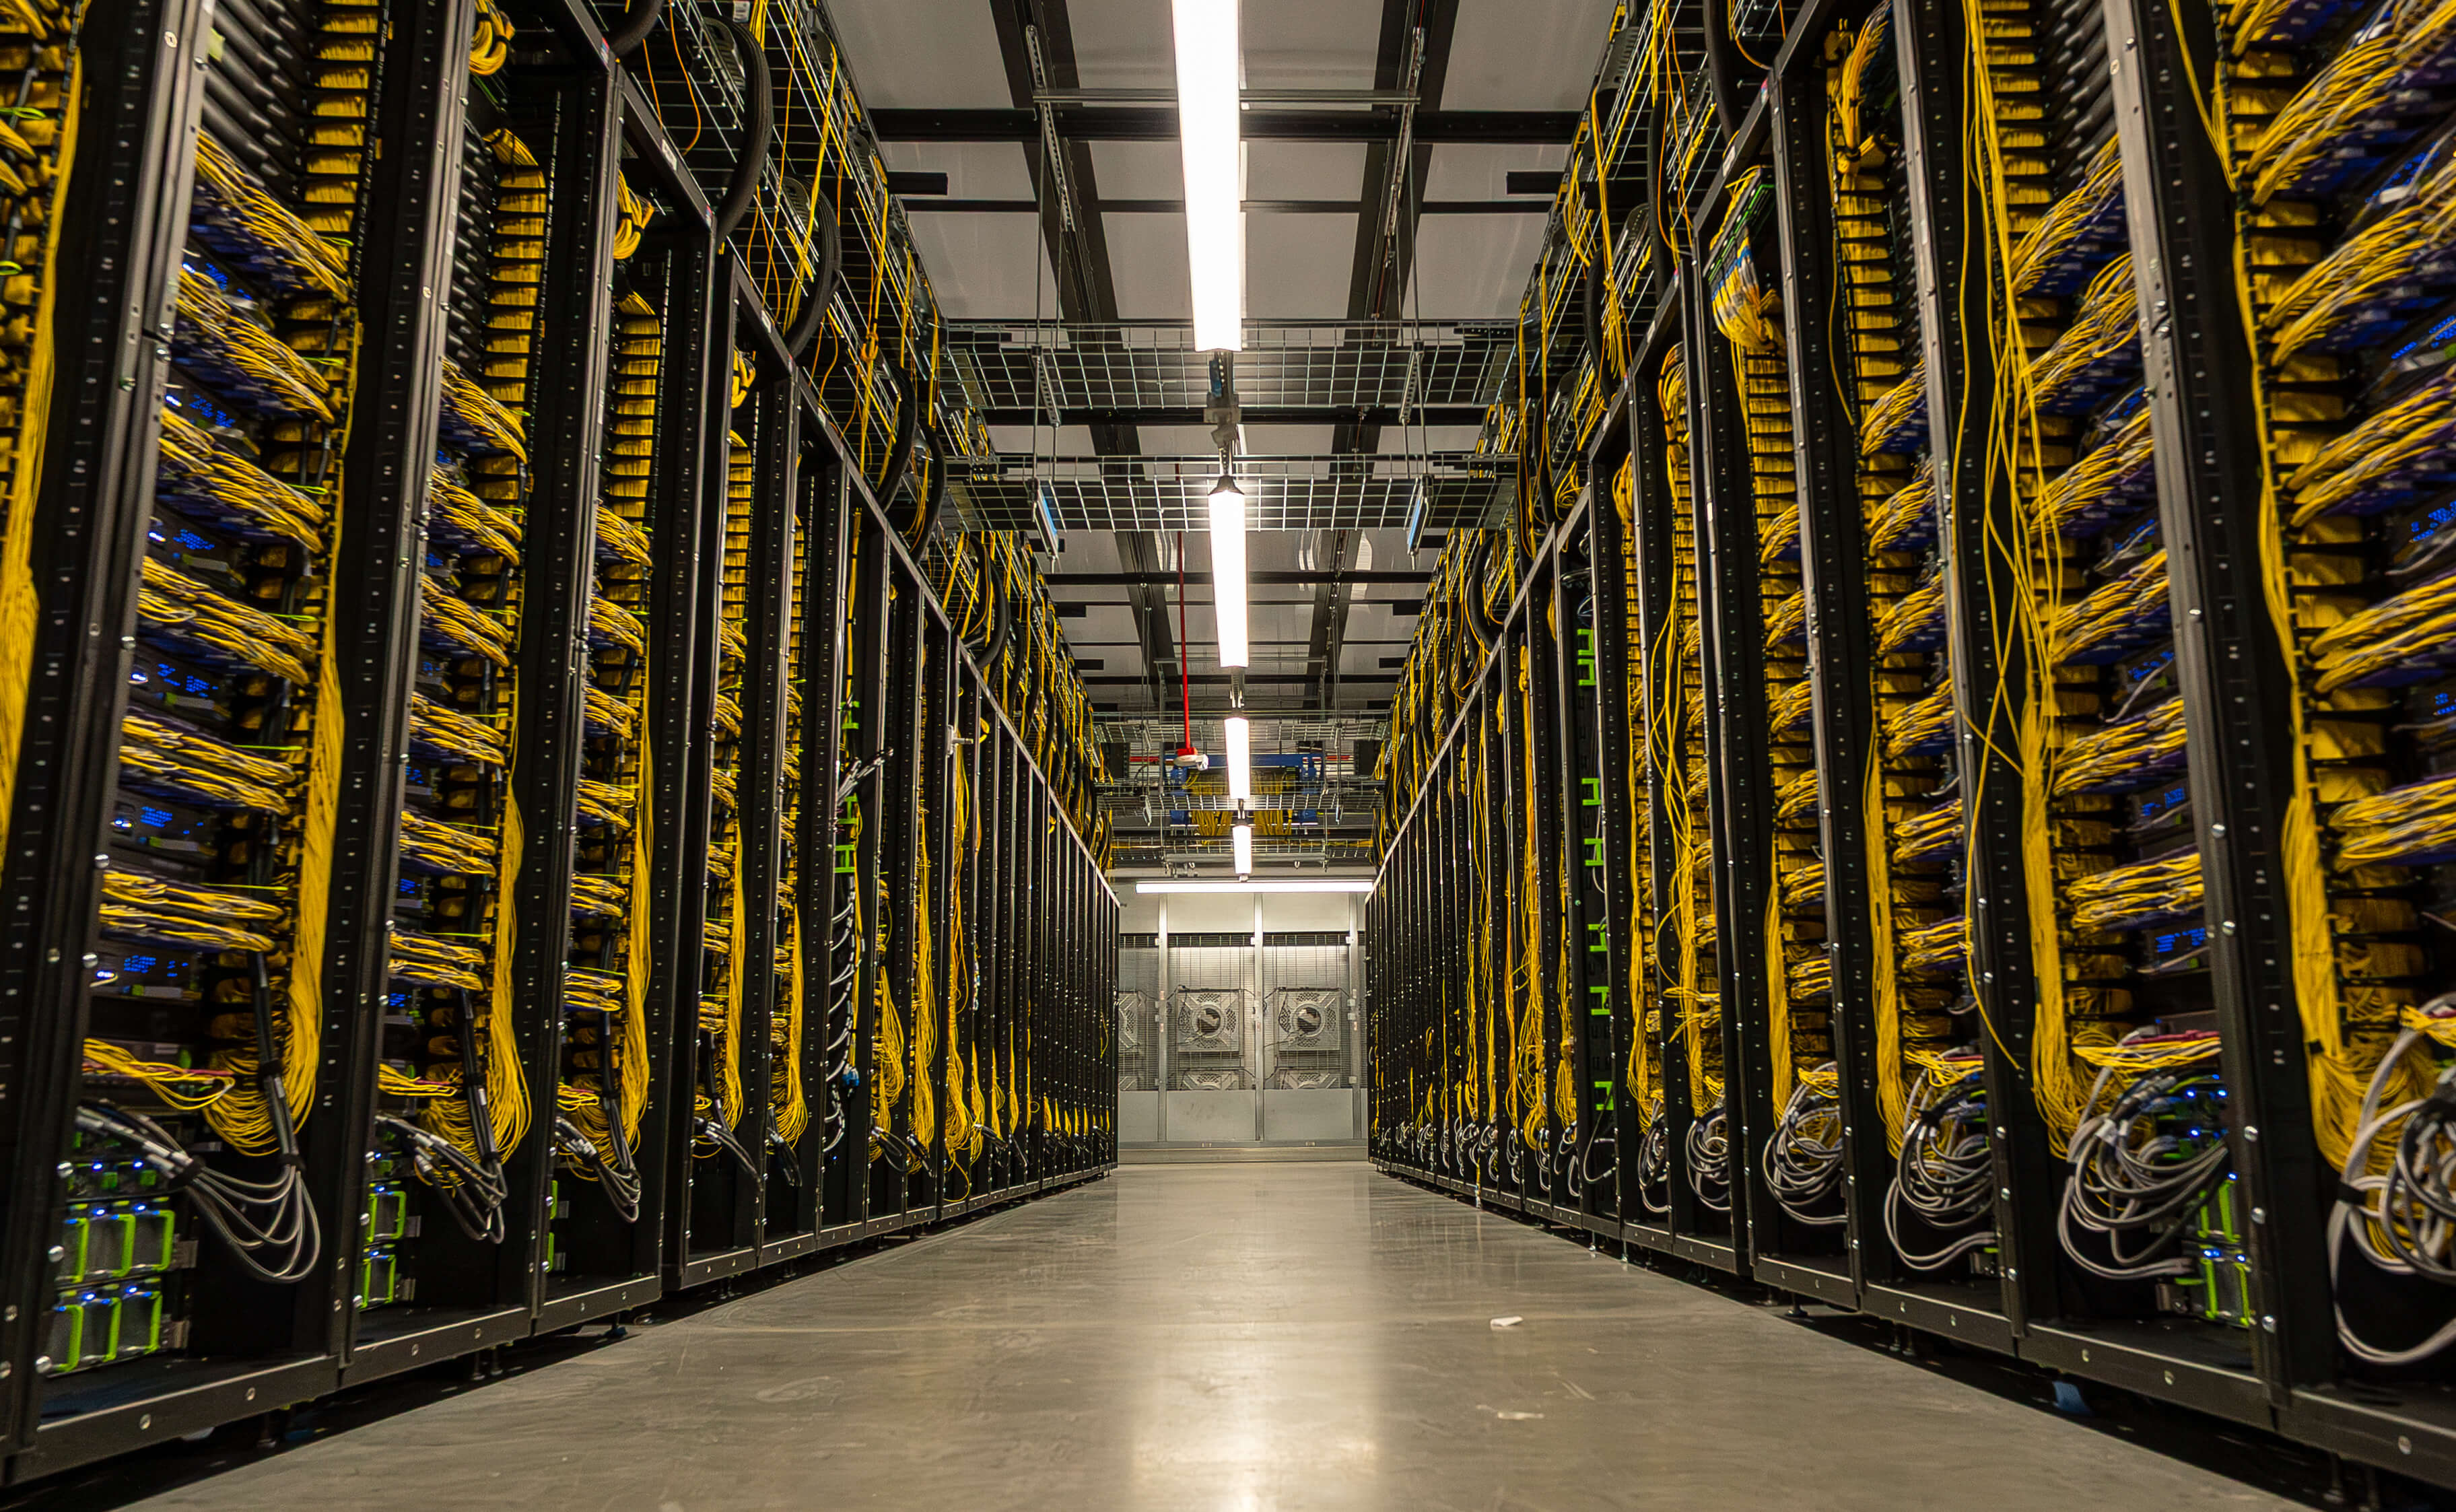
With the recent release of the Muse family of foundational models, we want to take you inside the infrastructure that has made it all possible. The first phase of Prometheus, our gigawatt-scale supercluster, is already complete and we’re working toward scaling it to comprise ~1 million GPUs. Prometheus also features technologies like closed-loop liquid cooling to help it operate efficiently. Right now, in New Albany, Ohio, Meta is undertaking its most ambitious AI infrastructure project to date. Prometheus, our gigawatt-scale supercluster, is an advancement in our infrastructure that is training the next generation of foundational models that will bring new AI experiences to billions of people. Two years ago, New Albany was a conventional data center site running web traffic. With advancements in hardware, networking and building design, we reworked this site to be home to training programs for frontier models. We’re building the supercluster in phases. The first phase has already been completed and was used to train our Muse foundational models , including the Muse Wonder models, our new frontier models that deliver state-of-the-art performance on personal and professional agentic tasks. Large training jobs require everything to work optimally to sustain their performance; an issue on a single host can slow down or stop the entire job, lowering its ‘goodput’. By focusing on improving our systems’ stability and reliability we were able to achieve more than 85% goodput for pre-training runs and more than 90% goodput for reinforcement learning (RL) runs of Muse Wonder. During these training runs, we were able to achieve an overall wall-clock mean time between interruptions (MTBI) of ~47k GPU hours. Since then, we have landed further changes across our fleet including firmware fixes to increase MTBI to more than 54K GPU hours, and we are constantly improving it. Now, we’re continuing to scale Prometheus with our next frontier models from Meta Superintelligence Labs in mind. https://engineering.fb.com/wp-content/uploads/2026/10/AIM-1210-Superclusters_Video_v1.mp4 The Prometheus supercluster is housed in Meta’s New Albany, Ohio, data center. The Supercluster: Unlocking New AI Capabilities Today, Prometheus comprises an array of hundreds of thousands of GPUs across multiple interconnected buildings, including traditional and AI-optimized data center buildings and rapid deployment structures, all tightly interconnected by miles of fiber and functioning as a single machine. This capacity allows us to pursue larger models and longer context windows than were previously practical. At full scale, Prometheus will comprise roughly 1 million distributed GPUs, all functioning in lockstep. Multiple Generations of AI Hardware Prometheus currently deploys two NVIDIA GPU platforms, with a third (based on NVIDIA’s Vera Rubin NVL72 ) arriving soon. Each represents a generational leap in performance and efficiency, leveraging our NVL72 rack architecture where 72 GPUs act as a single accelerator within the same network fabric. Catalina: NVIDIA GB200 Our first platform, Catalina , leverages the NVIDIA GB200 NVL72. We deploy the Ariel variant, a two-rack configuration in which 36 GPUs per rack are interconnected via NVLink to form a unified 72-GPU domain. Catalina provides improvements in raw compute and memory capacity compared to Grand Teton H100 . It leverages our Open Rack V3 (ORv3) high-power rack (HPR) structure, an open hardware design contributed to the Open Compute Project (OCP) . The Ariel variant of GB200 NVL72 pairs each NVIDIA Blackwell GPU with an NVIDIA Grace CPU and 2x NVIDIA ConnectX-7 400G NICs at a 1:1 CPU-to-GPU ratio, letting us deploy 800G of I/O per GPU earlier than the rest of the industry. We chose Ariel because the GB200 NVL72 scaled up nearly every other dimension relative to the NVIDIA H100: FLOPS, HBM bandwidth, scale-up bandwidth, and scale-up domain size, while scale-out bandwidth per GPU would have stayed at 400G. We expected that imbalance to cost performance, so we opted for a configuration that delivers 800G of scale-out per GPU. This also gave us more uniformity of spec as the region expanded over time and 800G scale-out became available. https://engineering.fb.com/wp-content/uploads/2026/10/AIM-1210-Superclusters_GB200_GIF_v1.mp4 The Catalina GB200 NVL72 features: 72 NVIDIA Blackwell GPUs with 13.4 TB of HBM3e (192 GB per GPU). 720 peak PFLOPS of FP8 training compute (1,440 PFLOPS at FP4). 130 TB/s peak NVLink bandwidth within the domain. 576 TB/s peak aggregate memory bandwidth. ~120 kW total system power across the two-rack pair. Clemente: NVIDIA GB300 NVL72 Our second platform, Clemente, moves to the NVIDIA GB300 NVL72 and improves on Catalina at both the GPU and the platform level. GB300 raises HBM capacity per GPU by 1.5x, from 192 GB to 288 GB, and dense FP4 throughput by a similar factor, while roughly doubling attention (softmax) acceleration. At the platform level, scale-out is no longer the constraint it was on the GB200 NVL72: NVIDIA ConnectX-8 SuperNICs deliver 800G per GPU natively, so the capability we deployed early on Ariel becomes the baseline. That, together with a 2:1 GPU-to-CPU ratio, allows Clemente to pack the full 72-GPU domain into a single rack, streamlining our physical deployment. Clemente can be deployed with our modular Air-Assisted Liquid Cooling (AALC) or use Facility Liquid Cooling (FLC) in our newly designed data centers. Serviceability also improves substantially, with reduced cabling. https://engineering.fb.com/wp-content/uploads/2026/10/AIM-1210-Superclusters_GB300_GIF_v1.mp4 The Clemente GB300 NVL72 features: 72 NVIDIA Blackwell Ultra GPUs with 20.7 TB of HBM3e (288 GB per GPU — 50% more than the GB200). Over 1 exaFLOP of peak FP4 compute. 130 TB/s peak NVLink bandwidth (1.8 TB/s bidirectional per GPU). ~135 kW rack power. 5-10% performance improvement over the GB200 NVL72. Connecting the Supercluster In traditional web services, the data center network transports requests and responses between services whose instances typically don’t require high bandwidth, high performance, and tight, lock-step coordination across many servers. Large-scale AI training requires all these, meaning the network that connects them is now an important part of AI workloads. To best address this, in addition to the standard data center network connecting servers, several years ago we added a second dedicated data network based on Ethernet, called the Back-End (BE) network, to enable direct GPU-to-GPU communication both within and across data center buildings. Large pre-training jobs partition the training into data-parallel model replicas, creating a hierarchy in network usage: Latency-sensitive and bandwidth-sensitive operations concentrate within a replica, while traffic that is more tolerant of higher latency and less bandwidth is scheduled between replicas. Our network is designed to match this hierarchy, with low-latency, high-bandwidth fabrics within buildings and an aggregation network connecting the building fabrics. We work closely with Meta Superintelligence Labs to ensure the parallelism design, traffic patterns, and communication algorithms and software are optimized to minimize exposure of any network communication. This keeps the GPUs as busy as possible and not waiting on the network. The Meta team has employed these networking concepts in earlier building-scale, 24K GPU clusters and our region-scale, 100K+ GPU cluster over the last several years, and we took them to a new level of scale and distance in Prometheus. Network Fabrics At the building level, each Ethernet-based fabric interconnects up to 20,736 GPUs through a high-bandwidth, low-latency multi-layer topology. Our initial design used a Disaggregated Scheduled Fabric (DSF) to mitigate the network congestion caused by training collectives that typically have a small number of large, long-lived network flows that collide under traditional load-balanci