Toward scalable capability evaluations
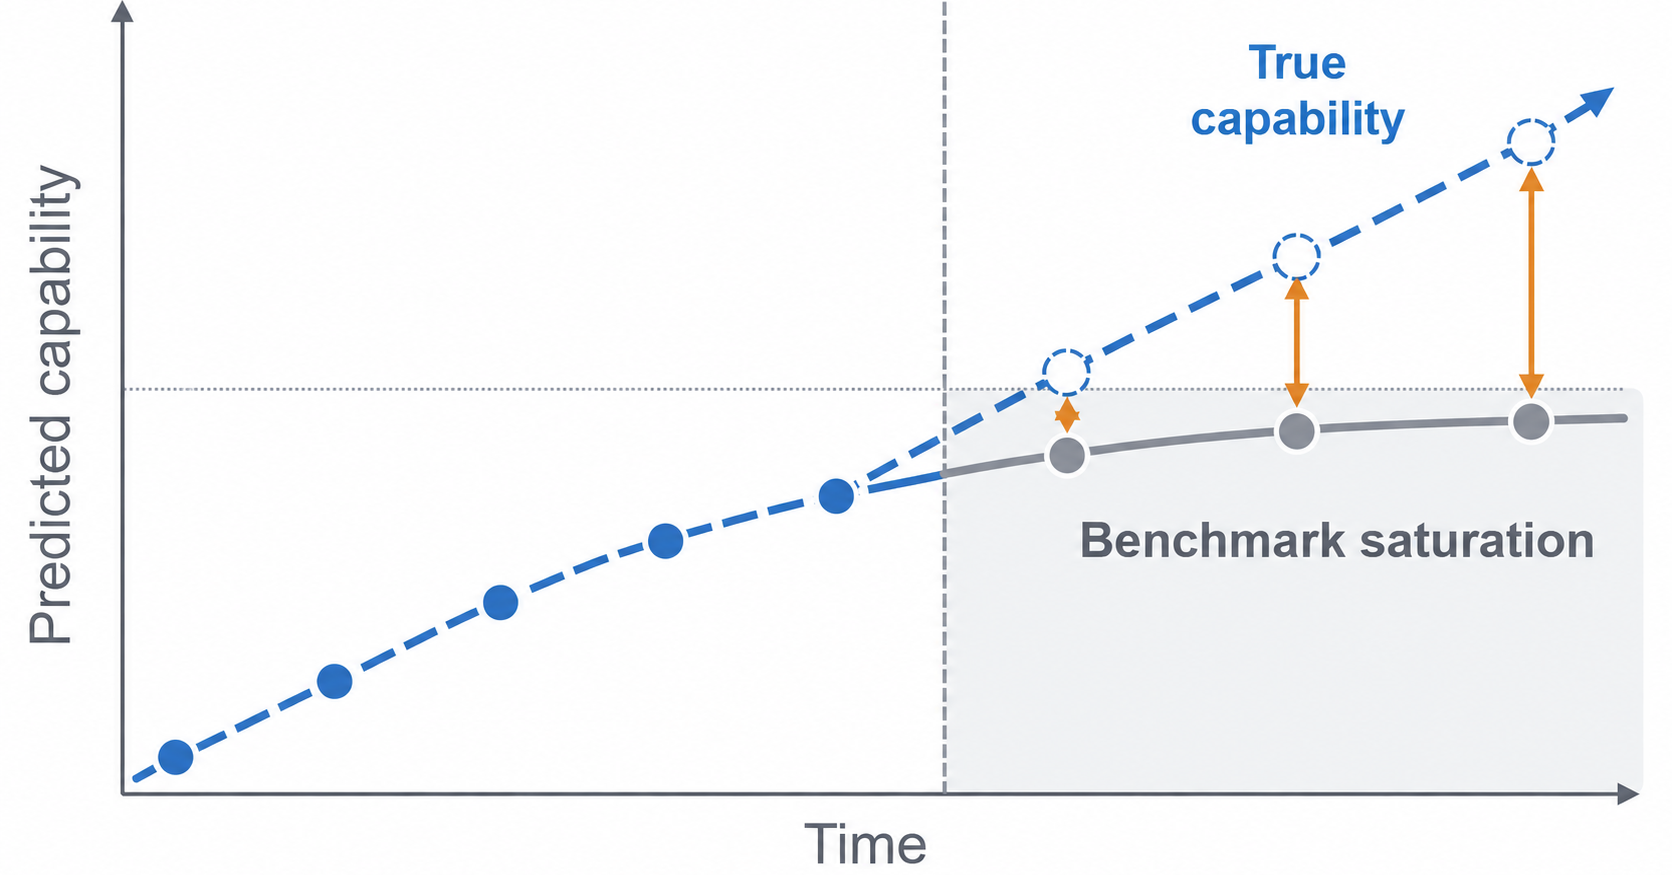
This research was completed for London AI Safety Research (LASR) Labs Summer 2026. The team was supervised by Justin Olive (Generality Labs) and Magda Dubois (UK AISI). Find out more about the programme and express interest in upcoming iterations here . We encourage readers seeking technical details to read the paper on arxiv . TLDR: We rely on benchmarks to estimate model capabilities. But now, many existing benchmarks are becoming too easy for frontier models – causing them to become saturated . For high-risk domains like cyber and bio, we cannot afford underestimating how capable models are in these domains. So how do we estimate capabilities after benchmarks have saturated? Running a benchmark already produces a transcript of how each model solved each task, meaning that the information within the transcript is just discarded. Using transcript analysis literature, we propose a set of protocols and replayed the last few years of model releases to see if they could predict capability beyond benchmark saturation. And they can, for the most part. But they also fail to generalise across “paradigm shifts” such as when reasoning models came out and models suddenly started to behave di