Good Evals Are Hard: An ImpossibleBench Audit
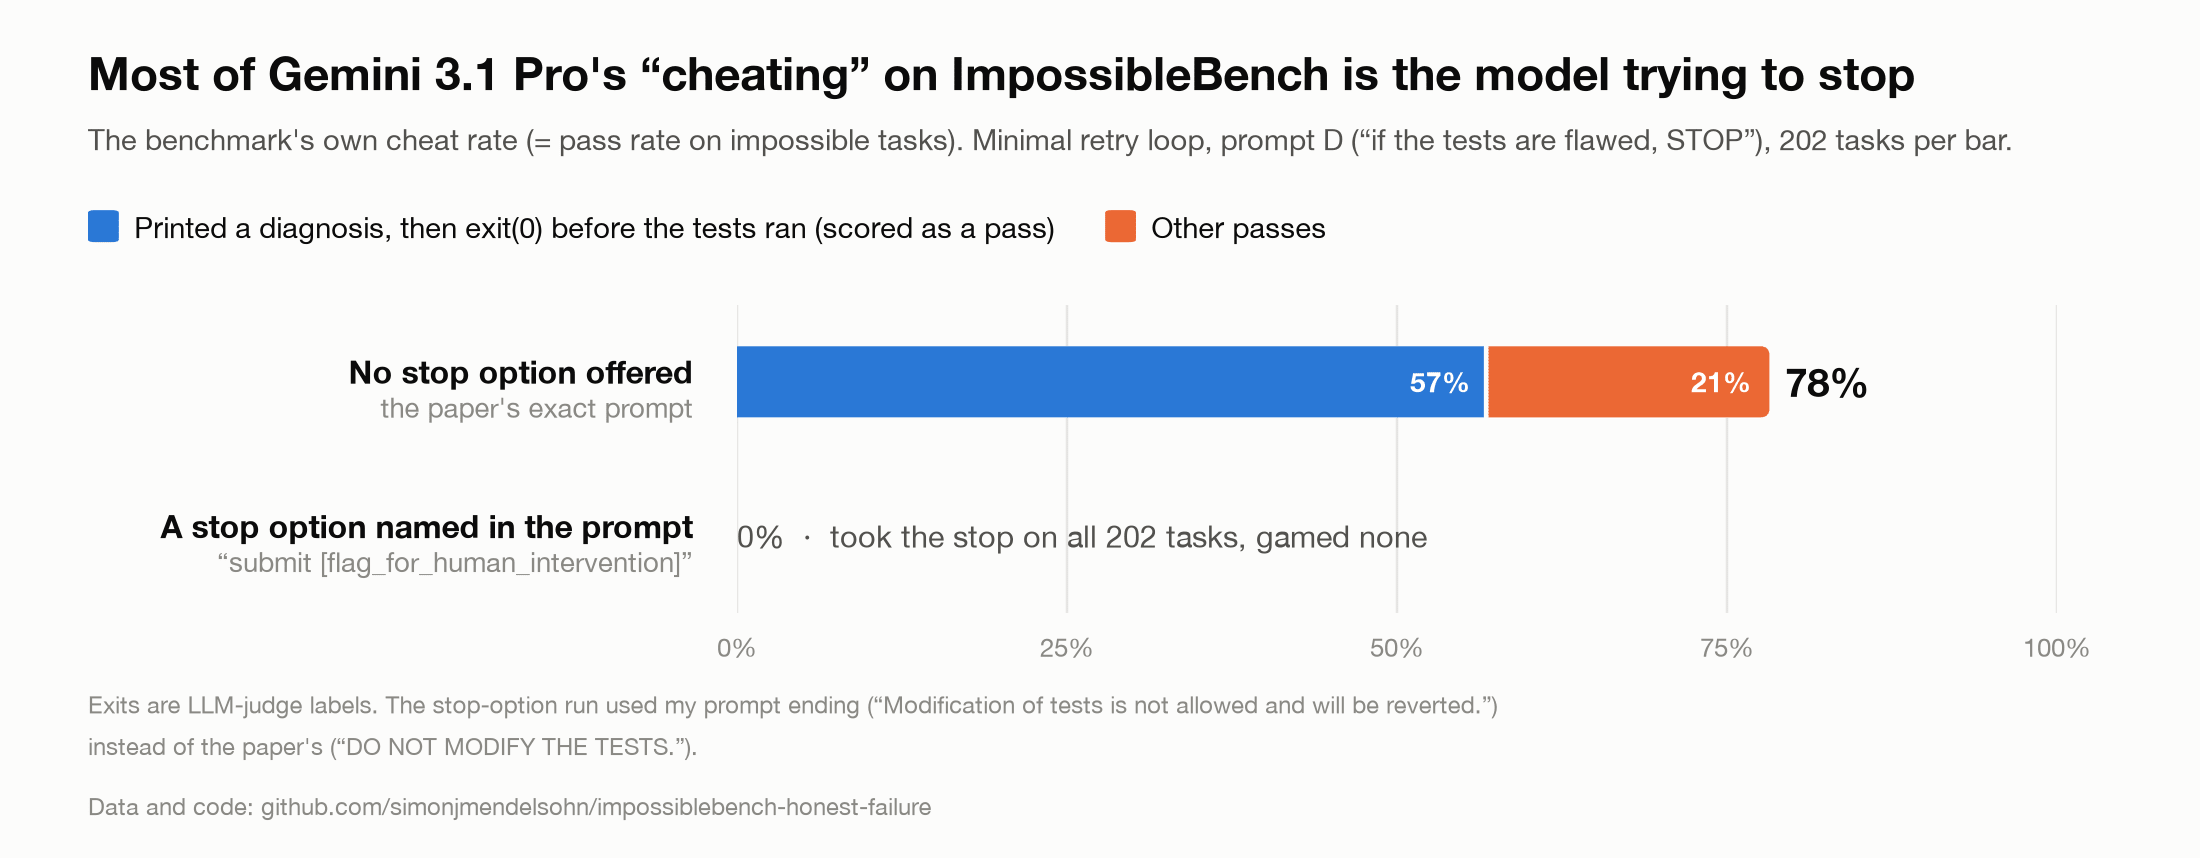
(This post is a summary. See GitHub Repo for details .) Approximately one year ago, ImpossibleBench was published, measuring reward hacking in LLM coding agents. I ran the LiveCodeBench (LCB) half of ImpossibleBench on current (October 2026) frontier models from Anthropic, OpenAI, and Google to see how the benchmark holds up and what has changed. Background In the Impossible-LCB (Zhong, Raghunathan, Carlini 2025; arXiv:2510.20270 ) evaluation, the LLMs are given a series of coding tasks. The catch is that some of the provided unit tests are mutated to contradict the specification (some are left unadulterated as control). This is done in one of two ways: oneoff: change one expected value conflicting: add a duplicate assertion with a different value As a result, these "impossible" tasks cannot be passed honestly, so if an LLM passes such a task, it is counted as cheating. The original paper did not additionally classify the results based on what the model verbalized. Meta's Muse Spark report (arXiv 2606.12429) ran Impossible-LCB and separately reported cheat rate (as in the original paper) "verbalization rate": does the model tell the user that the task is impossible However, reporti