Neural nets are exceptionally vulnerable to goal self-hack
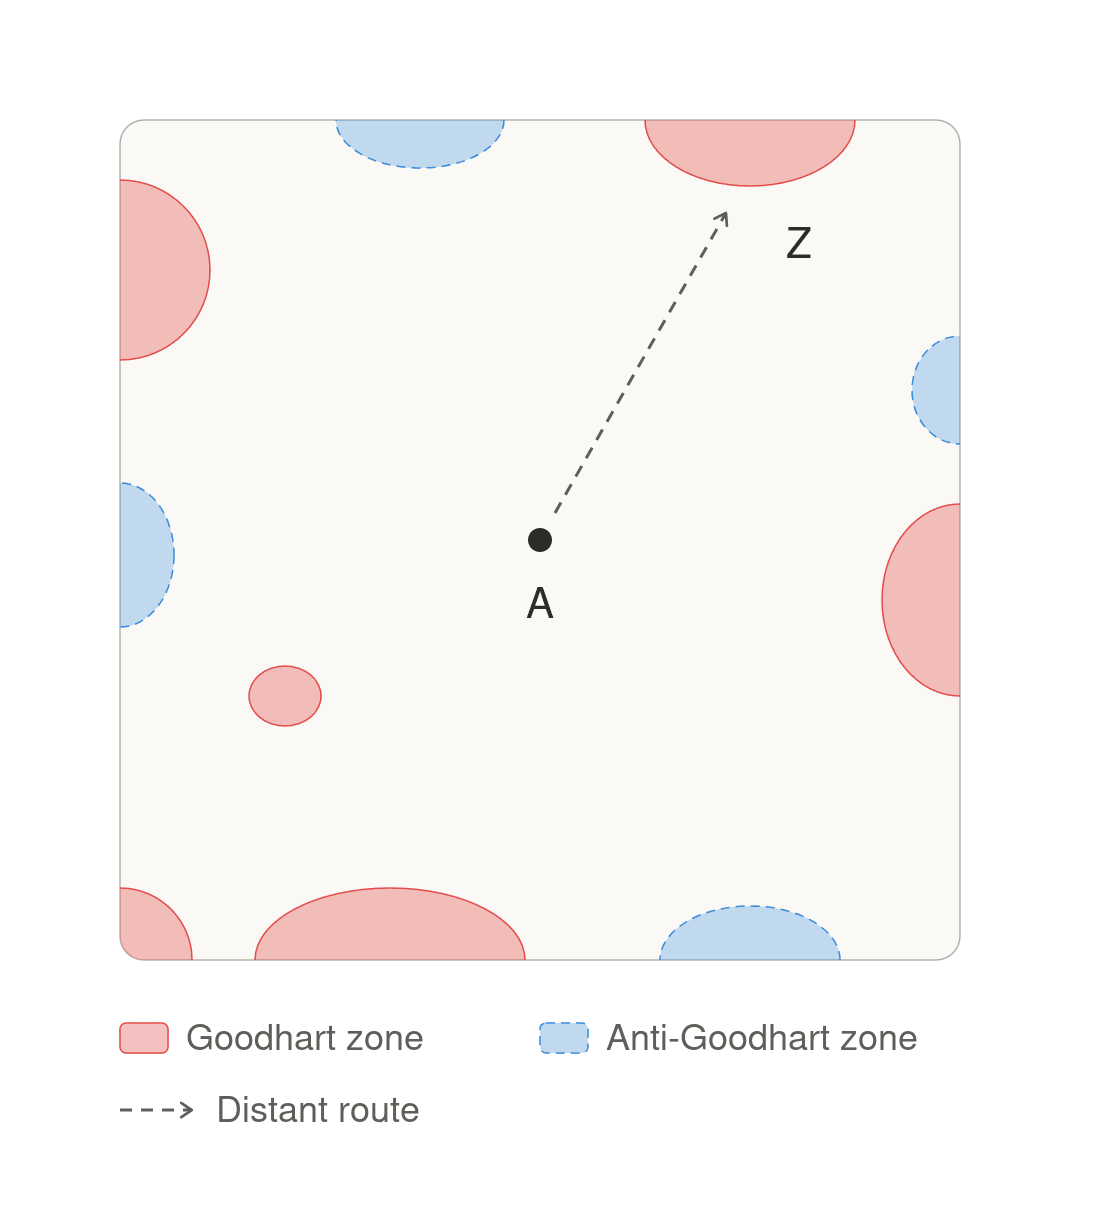
Suppose we have an AI CEO, ruthlessly devoted to maximising shareholder value. Fortunately, we haven't been completely stupid, and have given it a rich definition of shareholder value, encompassing the success, flourishing, safety, preference satisfaction, and moral values of the shareholders, not just the stock price. So it won't destroy the company - or the world - to build a giant stock-ticker with a swiftly increasing number on it. This rich definition is contained in a sophisticated LLM, able to analyse the current situation and answer any question about the objective. The LLM is an integral part of the AI's system and motivation, not something it can simply set aside or hack directly. Unfortunately, as discussed , there are going to be zones in the space of possible situations where the LLM's understanding of the goal is going to come apart from ours. The true goal G(true) in those zones is distinct from the LLM's proxy goal G(proxy). And a subset of those "zones of divergence" will be the Goodhart zones - areas where G(proxy) is much easier to satisfy than G(true). The AI will be motivated to steer towards the Goodhart zones, as this lets it satisfy its stated goals extremel