I spent a week testing whether LLMs can really "program weights." Reading weights: yes. Self-improvement: no. 20 steps of fine-tuning erase the edit
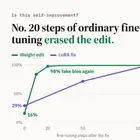
The Sparks post split this sub into "recursive self-improvement is here" and "nothing burger." I tested both claims on 4 real bugs in open models. Models can read weights. Blind Claude Opus sessions, given only raw weights and tools, fixed Whisper's hallucinations and a language-mixing bug 3 out of 3 times each. Edits work as patches. One rewired neuron cut fake biographies from 98% to 16% and left 98% of other answers word-for-word identical. But they don't stick. 20 steps of ordinary fine-tuning erased the fix completely. A model editing itself mid-training is fighting its own optimizer. So it's a sticky note on a frozen model for now. If someone finds a way to make edits survive training, that's when the self-improvement conversation gets real. Full write-up: https://kevinpl07.github.io/weight-patching/