Hacker News: frontier AIfine-tun*hugging faceqwen6h agoenergy 106
Show HN: Kvark Sparkle 27B – reasoning model trained to think with fewer tokens
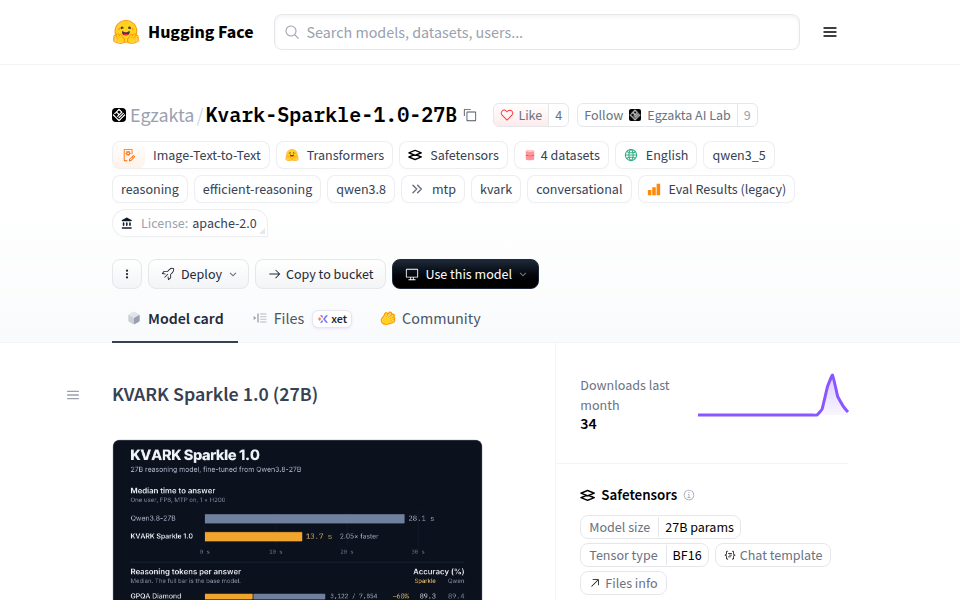
image: Hacker News: frontier AI
We had problems with Qwen spending too much time reasoning about tasks instead of doing them. That's why we decided to fine-tune it to use fewer reasoning tokens without losing accuracy. After a bunch of experiments we ended up with KVARK Sparkle 27B. On our evaluations it uses 34–67% fewer reasoning tokens while getting +- the same scores as the original qwen. Model is uploaded to Hugging Face with FP8 and GGUF versions available. I'd like to see how it performs on other people's tasks. To see where it can do worse than qwen. Comments URL: https://news.ycombinator.com/item?id=50336311 Points: 1 # Comments: 0
This source publishes only a summary in its feed, so the full article lives at the outlet. The link above and below goes to the original.