Large to Small Model Stitching Destroys What You Built It to Carry Along the Fit
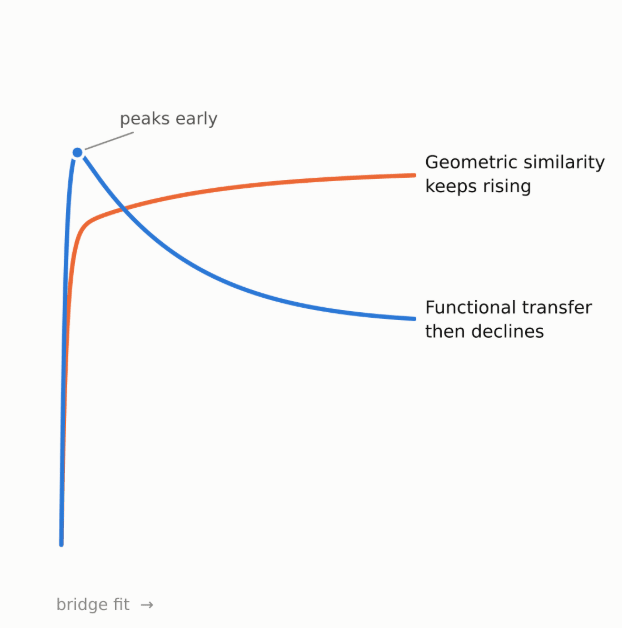
Independent research; early stage. Posting for feedback, particularly on whether the effect survives at realistic scale, and on prior work I've missed. Model stitching is extensively used in AI Safety infrastructure in reusing SAE & probes to make interpretability cheaper; transferring refusal, steering vectors so that small model can help align larger ones, cross architecture model diffing ( 1 , 2 ). In this post, I expand on Chen's et al. work on Model Stitching to transfer linear features across language models. They fit affine map (a.k.a. bridge in this article) between the residual streams of smaller and larger models, using a bidirectional loss with inversion weighted by α =1; trained to convergence, the usual practice. This work zooms in on findings of feature transfer from large to small along the fit where large model's surplus retention peaks early, then declines till final checkpoint. However, geometric similarity metric is blind to this trend, and it keeps rising through the fit. This is consistent across 3 different bridge objective (one directional MSE, Cosine loss and bidirectional MSE loss at α =1) and across the hook points, which indicates fitting a bridge to conv