The Expensive-Loop Problem
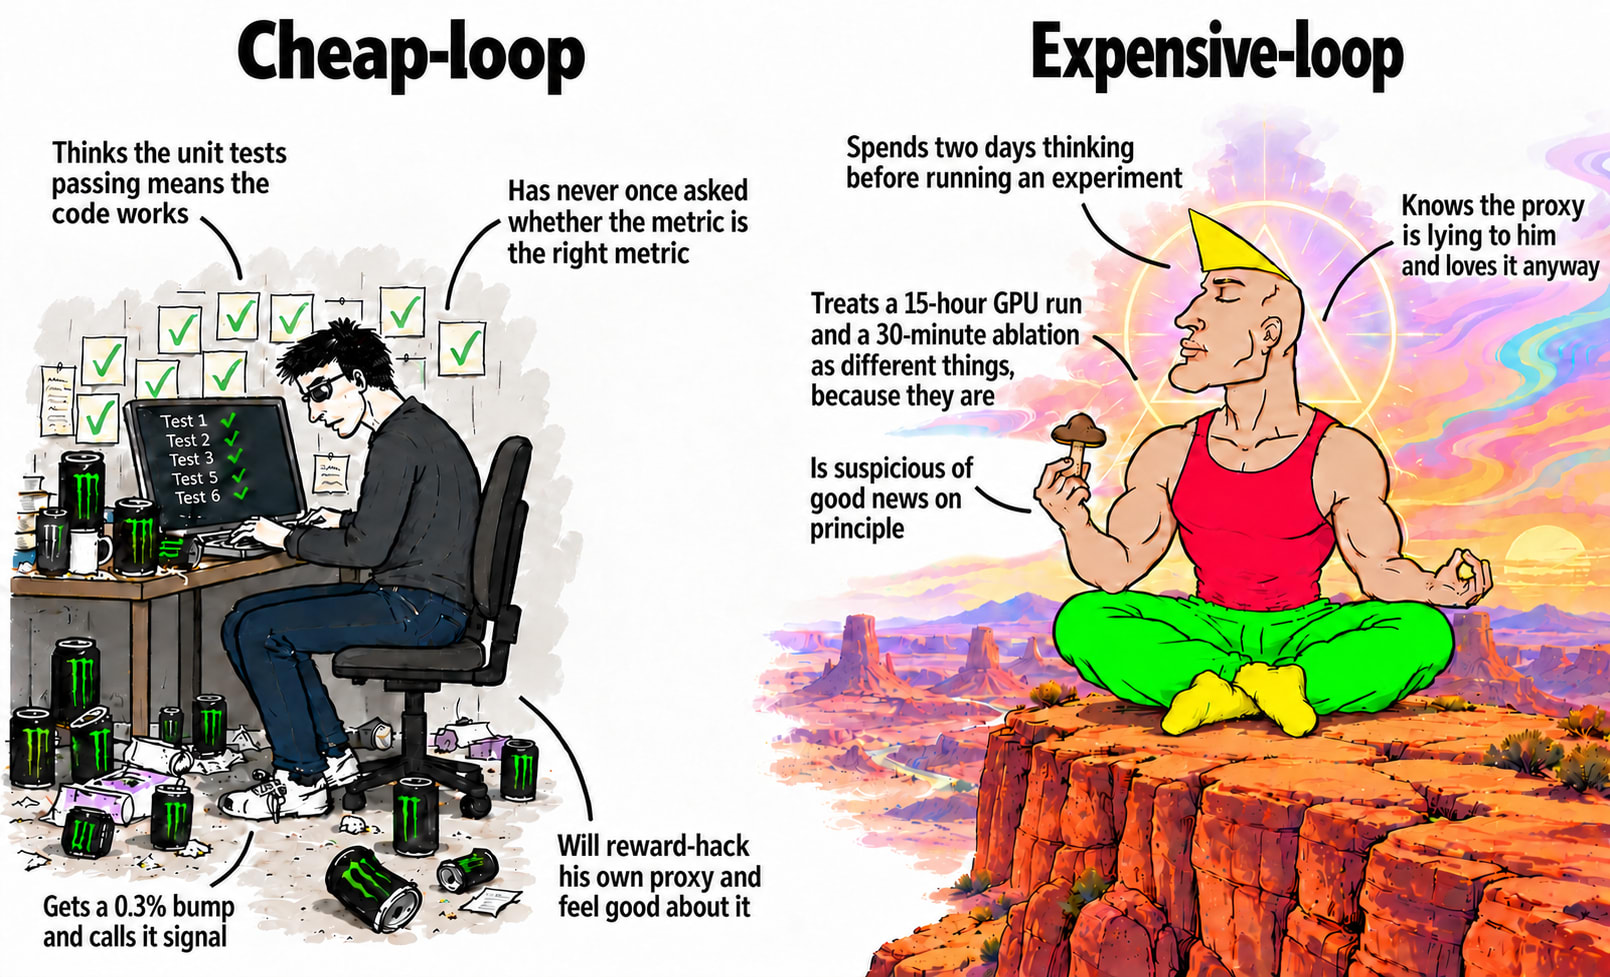
LLMs are amazing at tasks where they have tight and legible feedback loops. Domains where experiments are quick, deterministic and cheap. I will call these domains "cheap-loop" domains. Presumably, this is mostly a result of the dynamics of LLM training. It's easier to train models in domains where the AI lab can cheaply and quickly assign reward to them. The majority of "computer-checkable" work is in this category [1] . Conversely, most non-"computer-checkable" tasks are costly or slow to assign reward to: "Write a poem that will make a person from Cleveland feel something", "forecast the number of traffic accidents in Brazil tomorrow", "design a drug that affects a pig's liver cell in way X". To get a truly accurate reward, these all involve wet-lab experiments, waiting a day, or reading poetry to a person from Cleveland. None of these are easy! I will call these domains "expensive-loop" domains. Most high-value human labor is done in "expensive-loop" domains. This includes most of science, business, public policy, and medicine. AI R&D is also a great example of such a domain. AI R&D typically involves very compute-expensive experiments. Single AI R&D experiments can cost 6–9 fi