Fable 5.2 Leads the Singularity Gate: Benchmark for AI predicting paradigm-breaking scientific discoveries after model traning cutoff
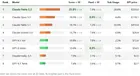
Claude Fable 5.2 is a major improvement on the Singularity Gate! It scores 25.8% while using 28.8% of a week's limit on a $200 plan. However, the models seem to hit a wall on the 12 Hard tasks, the most paradigm-breaking discoveries. Five models score between 7.6% and 8.0% . https://preview.redd.it/q8ok053aft0i1.png?width=719&format=png&auto=webp&s=67b330d9dcae61e41a3ec85b063b935231b2fbb9 https://preview.redd.it/c9z77rwnft0i1.png?width=832&format=png&auto=webp&s=69115f8b259ea69a4be138dff38d1083468996f3 I suspect that past a certain point, a bigger model doesn't do better in truly out-of-distribution areas as long as the base model behind the public models stays the same. On the 12 Hard tasks, Opus 5.5 and Fable 5.2 are level, and so are Sol and Astra. https://preview.redd.it/rxo81i6vft0i1.png?width=852&format=png&auto=webp&s=9fccef7f1fd2183623ea234cb348938914529f5c Fable 5.2 shows a slight improvement over Fable 5.1 on the Hard tasks in point estimate, but the difference is within the standard error. I assume Fable 5.1 was distilled from Anthropic's internal Model 2 and Fable 5.2 from Model 3. Such a small improvement (if any) between Anthropic base models on truly paradigm-breakin